Video by Hugging Face via YouTube
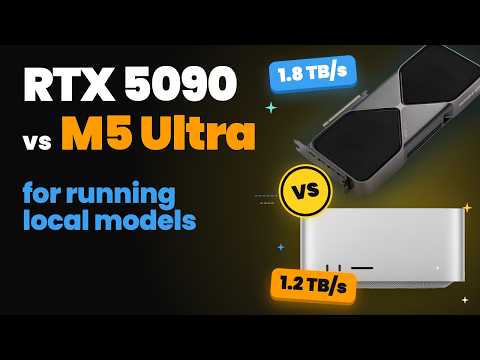
Apple’s M5 Ultra Mac Studio is shipping, so here is how it compares to NVIDIA’s RTX 5090 for running AI models locally.
wTopics covered:
– M5 Ultra vs RTX 5090 specs for local LLMs
– Qwen3.8-27B benchmark: prompt processing and token generation
– Multi-token prediction (MTP) speedups
– 32 GB VRAM vs 256 GB unified memory
– Tokens per second = bandwidth / model size
Resources:
– Qwen3.8-27B: [https://huggingface.co/Qwen/Qwen3.8-27B](https://huggingface.co/Qwen/Qwen3.8-27B)
– RTX 5090 llama.cpp runs of Qwen3.8-27B Q4_K_M: [https://huggingface.co/Qwen/Qwen3.8-27B/discussions/112](https://huggingface.co/Qwen/Qwen3.8-27B/discussions/112)
– MacStories M5 Ultra review (same prompts on both machines): [https://www.macstories.net/stories/m5-ultra-mac-studio-review-the-dream-mac-for-local-ai-agents/](https://www.macstories.net/stories/m5-ultra-mac-studio-review-the-dream-mac-for-local-ai-agents/)
Chapters:
0:00 Intro
0:19 The spec sheet
1:20 Same model, head to head
2:25 Memory: 32 GB vs 256 GB
2:41 What to take away